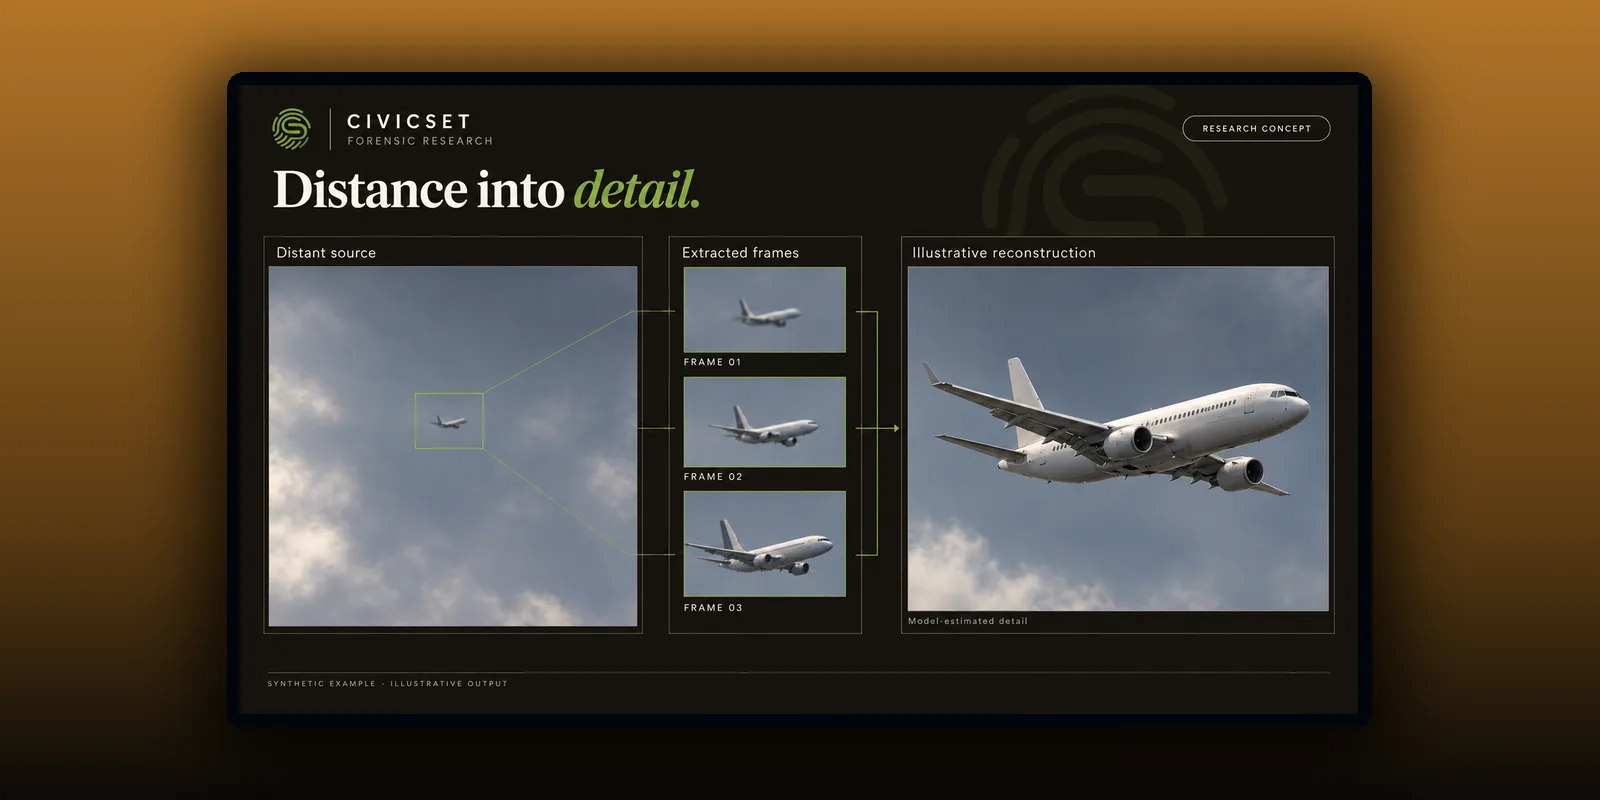
Every camera that shoots a burst or a video clip is quietly collecting more detail than any single frame contains. Hand motion, rolling shutter, and optical blur scatter that detail across neighboring frames at sub-pixel offsets: each frame samples the scene through a slightly different grid. Multi-frame super-resolution (MFSR) is the family of techniques that registers those frames against each other and fuses the scattered detail back into one image. The models differ enormously in what they accept as input and how they align it, and those two choices explain almost everything else about them.
This article compares three reference points in the modern landscape: BasicVSR / BasicVSR++ for continuous video, Deep Burst Super-Resolution (DBSR) for RAW sensor bursts, and the Burst Super-Resolution Transformer (BSRT), which pushed burst SR further with transformer-based fusion.
The classical foundation: shift-and-add
Before deep learning, MFSR was a registration-and-averaging problem. Estimate the sub-pixel translation of each frame against a reference, resample every frame onto a common high-resolution grid, and accumulate. The astronomy community's drizzle algorithm formalized this for undersampled telescope imagery, and the same idea (cross-correlation shift estimation, bilinear resampling into a float accumulator, then a final upscale) remains a respectable baseline when frames differ only by translation. Its ceiling is equally well understood: it models none of the optics, the noise, or the demosaicing, and it breaks down the moment motion stops being a pure translation. Everything below exists to remove one of those limitations.
BasicVSR and BasicVSR++: the video baseline done right
BasicVSR (CVPR 2021) is a study in restraint. The authors decompose video super-resolution into four functionalities (propagation, alignment, aggregation, and upsampling) and then assemble a bidirectional recurrent network almost entirely from generic parts: residual blocks for features, a small optical-flow network (SPyNet) for alignment, and straightforward feature fusion before upsampling. Because the recurrent stream passes information forward and backward through the whole sequence, each output frame can draw on every other frame, not just its temporal neighbors. The paper's claim is efficiency: it outperformed the state of the art of its time with fewer parameters and faster inference, and it doubles as a backbone you can extend. Its sibling IconVSR adds two such extensions (an information-refill mechanism and coupled propagation) for sharper 4× results at comparable speed.
BasicVSR++ (CVPR 2022) is where the extensions get systematic. It replaces the propagation structure with second-order grid propagation (each step reaches across the temporal grid two frames back, not one) and swaps flow-warped alignment for flow-guided deformable alignment, letting a deformable convolution refine the optical-flow estimate in feature space. The reported gain over BasicVSR is 0.82 dB PSNR at a similar parameter count. On the standard REDS4 benchmark (BI degradation), MMagic's published checkpoints put BasicVSR at 31.42 dB / 0.8909 SSIM and BasicVSR++ at 32.39 dB / 0.9069; trained on Vimeo-90K instead, BasicVSR reaches 37.20 dB on Vimeo-90K-T (BI). In competition, BasicVSR++ took three championships and one runner-up finish across the NTIRE 2021 Video Restoration and Enhancement tracks. Both models are maintained today inside MMagic (configs and pretrained weights for BasicVSR, IconVSR, BasicVSR++, and RealBasicVSR), which has effectively become the reference implementation.
Deep Burst Super-Resolution: treating the sensor honestly
DBSR (CVPR 2021, Bhat et al.) changes the input contract. Instead of processed sRGB frames, it consumes a burst of noisy, mosaicked RAW images (14 frames in its benchmarks) and must produce a clean, demosaicked, 4×-super-resolved RGB image in one pass. That contract folds three problems into one network: super-resolution, denoising, and demosaicing.
Architecturally, DBSR extracts deep features from every frame and aligns those embeddings explicitly using pixel-wise optical flow (a pretrained PWC-Net), rather than warping pixels before feature extraction. An attention-based fusion module then decides, per location, how much each aligned frame contributes. Training uses bursts synthesized from the Zurich RAW-to-RGB dataset through an inverse camera pipeline (translation, downsampling, mosaicing, and realistic noise) and evaluation runs on both that synthetic set (300 validation bursts; the paper reports 39.09 dB PSNR / 0.945 MS-SSIM) and the real-world BurstSR set of Samsung Galaxy S8 RAW bursts with DSLR ground truth (47.76 dB under the challenge's alignment-and-color-corrected metric, not comparable to the synthetic number, but indicative of how much information a real burst carries).
DBSR also defined the benchmark it competes on: the NTIRE 2021 Burst Super-Resolution Challenge adopted its datasets and evaluation protocol, with DBSR serving as the challenge baseline. The challenge itself was won by EBSR, a deformable-convolution approach that, like several of its successors, borrowed DBSR's problem statement wholesale.
BSRT: deformable alignment meets Swin Transformers
The Burst Super-Resolution Transformer (CVPR Workshops 2022, Luo et al.) starts from the same RAW-burst contract as DBSR but rebuilds the machinery. Alignment is a Pyramid Flow-Guided Deformable Convolution Network: optical flow (again from a pretrained PWC-Net) pre-aligns frames, and a pyramid of deformable convolutions refines that alignment in feature space, aggregating texture across frames that flow alone cannot register. The backbone is built from Swin Transformer blocks and groups, whose windowed attention captures long-range dependencies that convolutional burst fusion misses. BSRT won the real-world track of the NTIRE 2022 Burst Super-Resolution Challenge and set a new state of the art on both synthetic and real BurstSR data, training on the NTIRE 2021 synthetic and real sets. An extended journal version, BSRT++, followed in 2024. The reference implementation is MIT-licensed PyTorch, with one practical caveat: it builds DCNv2 (deformable convolution) from source, so reproducing it takes more than pip install.
The wider map
Two neighbors are worth knowing. EBSR, the NTIRE 2021 winner mentioned above, introduced the enhanced deformable-convolutional alignment grid that BSRT's flow-guided variant builds upon. And in the satellite domain, the ESA Proba-V challenge produced a family of non-sequential MFSR networks (DeepSum and its successors) that register and fuse as few as nine low-resolution frames of the same ground patch; a compact PyTorch reimplementation uses spatial-transformer registration nets with a two-stream fusion module, and is a readable example of the whole genre.
Comparing them, dimension by dimension
Input domain
- BasicVSR/++: continuous sRGB video: frames are dense in time and already processed.
- DBSR: RAW Bayer bursts (RGGB, noisy, mosaicked), 14 frames, taken seconds apart.
- BSRT: the same RAW burst contract as DBSR.
- Satellite MFSR: short non-sequential bursts (9+ frames) of the same static target.
The RAW-versus-sRGB split is the most consequential line in the field: a RAW-domain model inherits denoising and demosaicing as part of the task, and cannot be fed ordinary video without an inverse pipeline.
Alignment mechanism
- BasicVSR: optical-flow warping of features between recurrent steps.
- BasicVSR++: flow-guided deformable alignment: flow proposes, DCN refines.
- DBSR: pixel-wise optical flow applied to deep feature embeddings.
- BSRT: pyramid flow-guided deformable convolution: flow pre-alignment refined across scales.
The progression is consistent across both families: pure flow gives way to flow-conditioned deformable convolution, because bursts and hard video motion violate flow's smoothness assumptions.
Aggregation and fusion
- BasicVSR/++: implicit fusion inside the recurrent stream (plus IconVSR's explicit information refills).
- DBSR: attention-weighted per-location fusion of aligned embeddings.
- BSRT: Swin Transformer burst fusion over aligned multi-frame features.
What the network owes you
A video model owes one upsampled frame per input frame. A burst model owes a single clean RGB image (super-resolution plus denoising plus demosaicing) from the whole burst. The second contract is harder, which is why RAW burst models can post PSNR numbers that look (and are) incomparable with sRGB video benchmarks.
Efficiency and practicality
BasicVSR's founding claim was efficiency against then-SOTA, and it still holds: it remains the sensible default when compute matters. BasicVSR++ buys 0.82 dB for a similar parameter count. The burst models are a different regime (trained on multi-GPU setups with patch-based crops) and BSRT adds a from-source DCNv2 build to the bill.
Code, weights, and licenses
- BasicVSR / IconVSR (Apache-2.0), with maintained configs and weights in MMagic.
- DBSR and the NTIRE21 challenge toolkit.
- BSRT (MIT).
Further reading
- BasicVSR: The Search for Essential Components in Video Super-Resolution and Beyond, Chan et al., CVPR 2021, plus the project page.
- Deep Burst Super-Resolution, Bhat et al., CVPR 2021.
- BSRT: Improving Burst Super-Resolution with Swin Transformer and Flow-Guided Deformable Alignment, Luo et al., CVPR Workshops 2022.
- MMagic config readmes for BasicVSR and BasicVSR++ carry the full benchmark tables and training recipes.
The unifying lesson across all of them is the one the classical shift-and-add baseline already taught: alignment quality bounds everything downstream. What changed is that alignment moved into feature space, became learnable, and now carries most of the performance gains the field has made since.